From code, to simulation, to physical machines.
Independent AI benchmark lab. Same task, frozen prompt, every failure kept.
Qwen 3.8 Flash vs DeepSeek V4.1 Flash vs GLM 5.3 Flash vs Gemini 3.8 Flash
No universal winner. The cheap models were brutally task-specific. Qwen led several game and voxel rounds. DeepSeek produced the better CAD submission. GLM was the only model to pass the apple-stem grasp. Gemini led several robot tasks.
Simulation capture
Experiments
All experiments →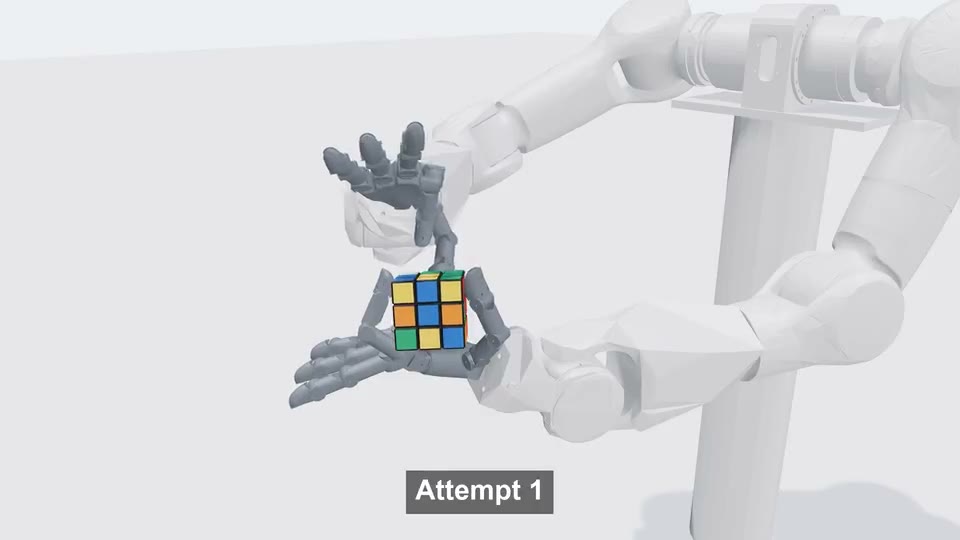 Qwen 3.8 Flash vs DeepSeek V4.1 Flash vs GLM 5.3 Flash vs Gemini 3.8 FlashThere was no universal winner. Flash-model performance was brutally task-specific.
 Claude Opus 5 across nine game-building testsOpus 5 delivered the strongest detail in several rounds. It also made the efficiency argument against itself.
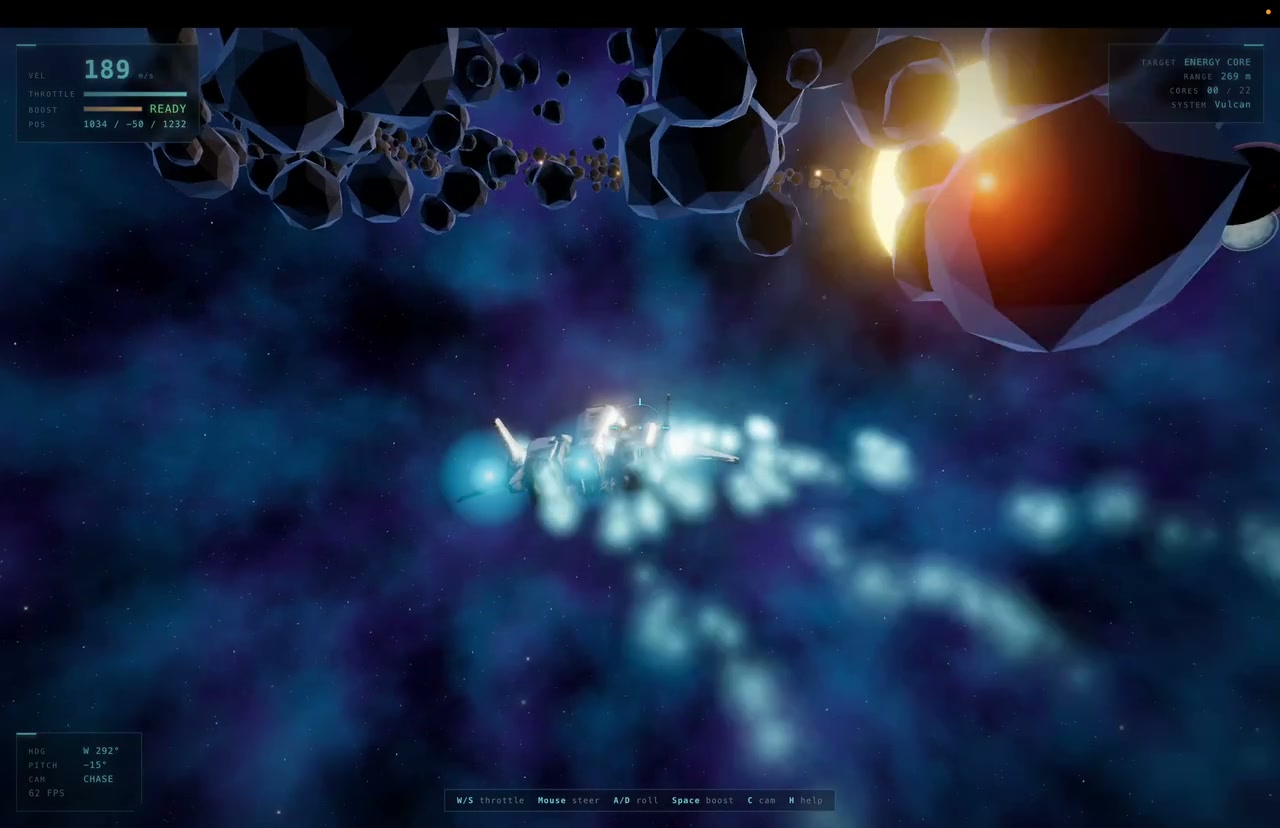 I Gave Qwen3.8 Max, Kimi K3, GPT-5.6 and Fable 5 the Same 9 Game TestsKimi K3 was more consistent; Qwen's visual-agent workflow was not reliable enough to win overall.
 Kimi K3 vs GPT-5.6 SOL vs Claude Fable 5: 9 Game TestsFable 5 sets the visual ceiling. Kimi K3 wins on value. GPT-5.6 Sol Ultra is the practical middle when technical coherence matters without paying Fable’s full cost.
 GPT-5.6 vs Claude Fable 5: Same Prompts, 7 AI Game-Dev TestsFable sets the visual ceiling. Sol Ultra wins the value argument.
Models
All results →| Model | Provider | Runs | Avg cost | Avg time |
|---|---|---|---|---|
| GLM 5.3 Flash | OpenCode Go | 34 | $1.23 · includes provider estimates | 1h 14m |
| GPT-5.6 Luna | OpenAI Codex | 27 | $2.03 | 23m 26s |
| GPT-5.6 Sol | OpenAI Codex | 26 | $8.45 | 39m 15s |
| Grok 4.6 | Grok CLI subscription | 26 | $4.85 · includes provider estimates | 33m 25s |
| DeepSeek V4 Flash | OpenCode Go | 25 | $0.26 | 1h 56m |
| Claude Opus 5.5 | Anthropic | 24 | $52.80 | 30m 29s |
| GPT-6 Astra | OpenAI | 24 | $31.94 | 1h 12m |
| Claude Opus 5 | Anthropic | 23 | ≥$68.52 | 2h 31m |
Method
Methodology →- Same taskEvery model gets the same frozen target and prompt.
- One attemptNo human follow-up or rescue pass after submission.
- Failures retainedFailed and partial runs stay in the record.
- No run, no scoreUntested systems stay untested — including physical machines.